Fine-tuning Qwen3-ASR for Sinhala – Part 4: Training on a Mac, the Same Way the App Runs
In part 3 the data was ready. This part is about the trainer, and the rule that ended up shaping all of it.
Change of plan: the Mac is the GPU
The original plan was to rent an NVIDIA GPU for a day and use Qwen’s official fine-tuning script, which is written for PyTorch on NVIDIA hardware. The app runs its models with Apple’s MLX, so the trained model would then be converted from one to the other.
That conversion bothered me. Any small difference between how PyTorch and MLX run the model would only show up as extra errors after training, with no easy way to tell whether the training or the conversion was to blame. So I decided to train on my Mac instead, with MLX Swift, on the same model code the app uses (mlx-audio-swift). That way the model trains on exactly the audio features, prompt and weights it will see in the app.
The memory works out. The model has 782 million parameters, and a full fine-tune keeps three 32-bit copies of each: the weights, and two running averages the optimiser (AdamW) needs. That’s 9.4 GB, well within a 48 GB M4 Pro MacBook Pro, with room left for the training batches. The price is speed: one pass over the data takes a night, instead of an hour or two on a data-centre GPU. For a model I’ll train a handful of times, no cloud bill and no conversion is a fair trade.
Training starts from the exact model the app ships (mlx-community’s 8-bit Qwen3-ASR, converted back to 32-bit at load). Starting from Qwen’s original release would have meant another download and a conversion the app never ran. The replay labels from part 3 came from this model too, so the replay set starts with nothing to learn.
The trainer
There’s no ready-made tool for fine-tuning this model with MLX, so one was written in Swift: under 3,000 lines, with 45 unit tests, in LiveTranscribe-Sinhala on GitHub. It’s small because the model code already exists in the app’s library. Its job is to feed the model the right inputs and adjust the weights:
- The prompt. Each example is laid out exactly as the app prompts the model: a system turn,
one slot for each piece of audio, then the answer,
language Sinhala<asr_text>followed by the transcript. The model is only scored on the answer. - Batches. Every update learns from 128 recordings, run through the model in smaller groups sized by length, so a batch of long sentences doesn’t run out of memory.
- The optimiser. AdamW with a short warm-up and a linear decay. A unit test checks it against values worked out by hand.
- Surviving the night. The full training state is saved every 30 minutes, so a crash or a reboot costs at most half an hour. A lighter copy of the model is saved four times per pass, with its error rate on 500 held-back recordings, so I can pick the best one afterwards.
Copy the app, quirks included
The first time the trainer ran a real batch, it crashed: the model produced fewer pieces of audio than the prompt had slots for. Tracking that down gave me the most important rule of the project. The trainer has to give the model exactly what the app gives it, including the app’s quirks. A model learns whatever its inputs look like in training. If the app then feeds it something slightly different, the difference shows up as errors that are very hard to trace.
Three things turned up.
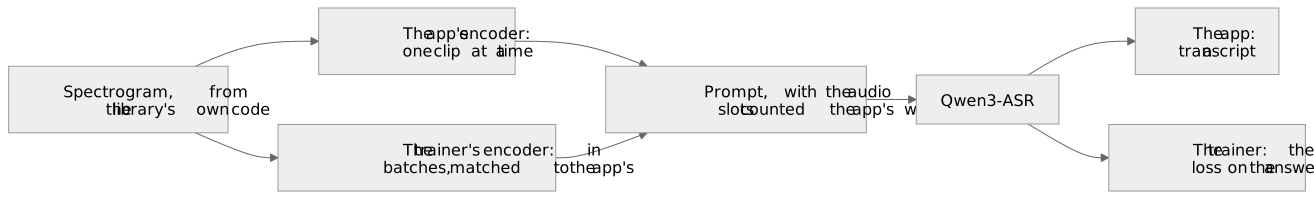
1. The audio slots are counted with a fraction
Qwen3-ASR gets 13 slots in the prompt for every second of audio. Qwen’s reference code counts whole seconds with integer division, then adds a little for the part-second left over. The Swift library does the same sum, but its division happens in floating point, so the leftover part-second gets counted twice. A clip of about 5.9 seconds gets 88 slots where Qwen’s code gives 77. The encoder only makes 78 pieces of audio for it, so the last 10 slots keep a placeholder.
The model copes with it: the app’s English is as good as Qwen’s published numbers. So it’s not a visible bug, but it is what the app does. The trainer copies the count exactly, placeholders and all, and a check compares it with the library’s on real clips. If the library ever fixes this, the Sinhala model will need testing again, because its inputs will change. I still need to report it upstream.
2. The app’s encoder can’t do batches
The app only ever transcribes one clip at a time, so the library’s audio encoder was never written for batches. Given several clips, it lays out its attention windows (the stretches of audio the encoder looks at together) as if the clips were one long recording, and the end of one clip bleeds into the start of the next. Training needs batches, so the trainer has its own encoder that runs the model’s own layers but keeps each window inside its clip. On 32 clips, the trainer’s batched output matches the app’s one-at-a-time output to within 0.00001.
3. The audio features were computed wrongly
Before the model hears anything, the sound is turned into a spectrogram: a picture of which pitches are loud at each moment, in 128 bands. Qwen trained its model on spectrograms made a particular way (the same way as Whisper’s). While checking the library’s code against Qwen’s, it turned out the version the app used spaced those bands on a different scale (HTK instead of Slaney), and shaped each 25 millisecond slice of audio slightly differently. The library’s maintainers had already found and fixed this upstream a few weeks earlier (#247), after noticing it on noisy recordings, but the fix wasn’t in a release the app could pick up.
It sounds like a small thing. I measured it on the 647 English test recordings in FLEURS, then again with hiss added at 10 dB signal-to-noise (about what you’d notice on a phone call):
| Qwen3-ASR on FLEURS English | Clean | With hiss |
|---|---|---|
| The app’s version of the library | 5.46% | 16.38% |
| With the corrected spectrogram | 4.96% | 9.78% |
Same model, same recordings, only the spectrogram changed. With hiss, the fix removes 40% of the word errors. On the clean set it helped 85 recordings and hurt 42, and with hiss it helped 332 and hurt 57, so it isn’t chance.
This made the decision for me. Train the Sinhala model on the old spectrograms, and the app could never take the fix without breaking Sinhala. Train it on the corrected ones, and the app has to update the library first, which it should do anyway for its English. So the trainer uses the corrected library, and it takes its spectrograms from the library’s own code rather than a copy, so the two can’t drift apart again. The replay set was relabelled with the corrected version (a third of the labels changed), and the app’s library update has since been merged.
Checks before a night-long run
A training run that’s quietly wrong wastes a night and teaches you nothing. So the trainer has a
check command that has to pass before any long run. It takes about 30 seconds:
| Check | Result |
|---|---|
| Each example tokenises the same as the app’s prompt would | 32 of 32 |
| Audio slots counted the way the app counts them | 32 of 32 clips |
| Batched encoder against the app’s, clip by clip | within 0.00001 |
| A batch’s loss equals the sum of its clips’ losses | to one part in a million |
| Shown its own replay labels, the model predicts every next token itself | all 561 tokens |
| Every part of the model gets a learning signal | all 301 encoder and 310 decoder tensors |
| The 32-bit copy being trained transcribes like the app’s 8-bit model | 15 of 16 identical |
| 16-bit arithmetic points the learning signal the same way as 32-bit | cosine similarity 0.995 |
The fifth one matters most. Training shows the model the correct transcript so far and asks it for the next token (this is called teacher forcing). Doing that with the untrained model and its own labels, and getting its own answer back for every token, proves the prompt, the audio and the loss are all wired the way the model expects.
What I learnt
- Train on exactly what the app will feed the model. Every difference between the trainer and the app is a source of errors that the training numbers won’t show.
- Copy the quirks too, and write them down. The fractional slot count is odd, but it’s what the model sees. Changing it later means testing again.
- Read your library’s preprocessing against the reference implementation. The spectrogram fix was worth about 9% of the errors in clean English and 40% with noise, before any training.
- Fixing the model’s inputs is a commitment. Once a model is trained on a front end, the app is tied to it.
- Prove the wiring before a long run. Teacher forcing on the model’s own labels is a very good single check.
- A 48 GB Mac is enough for a full fine-tune of a 0.6B model, as long as you don’t need it done in an hour.
Next: the first real training run, and what went wrong in it.